
On this page
Apache Spark makes distributed processing look like ordinary DataFrame code, which is both its strength and the source of most production problems. A job that took ten minutes last month takes two hours today; one task out of two thousand runs for forty minutes; executors die with out-of-memory errors on a cluster that has plenty of memory. None of these is random. Each follows from how Spark turns code into stages, shuffles and tasks, and each shows up in the query plan and the Spark UI before anyone needs to guess.
This article goes inside a Spark job as of November 2025, with Spark 4.0: lazy evaluation and planning, stages and shuffles, join strategies, Adaptive Query Execution (AQE), partitions and skew, and the executor memory model. Where Spark sits among the other tools in a data platform is covered in the earlier article on the modern data stack; this one stays inside the engine. The sample code turns each behaviour into a test that runs on a laptop.
What changed in Spark 4.0
Spark 4.0.0 was released in May 2025, with over 5,100 tickets resolved. Three changes matter for existing jobs. JDK 17 became the default and JDK 8 and 11 were dropped, alongside Scala 2.12. ANSI SQL mode is now on by default, so overflows, invalid casts and division by zero raise errors instead of quietly producing nulls. Spark Connect, which separates the client from the cluster, gained a lightweight Python client and a spark.api.mode setting to switch it on. Support for Apache Mesos was removed, leaving Kubernetes, YARN and the standalone manager.
Jobs that ran cleanly on Spark 3.x can fail on 4.0 because bad values that used to become nulls now raise errors. Run existing jobs against 4.0 in a test environment with ANSI mode on, fix the data or the casts each error points to, and only set spark.sql.ansi.enabled=false as a temporary measure.
From code to tasks
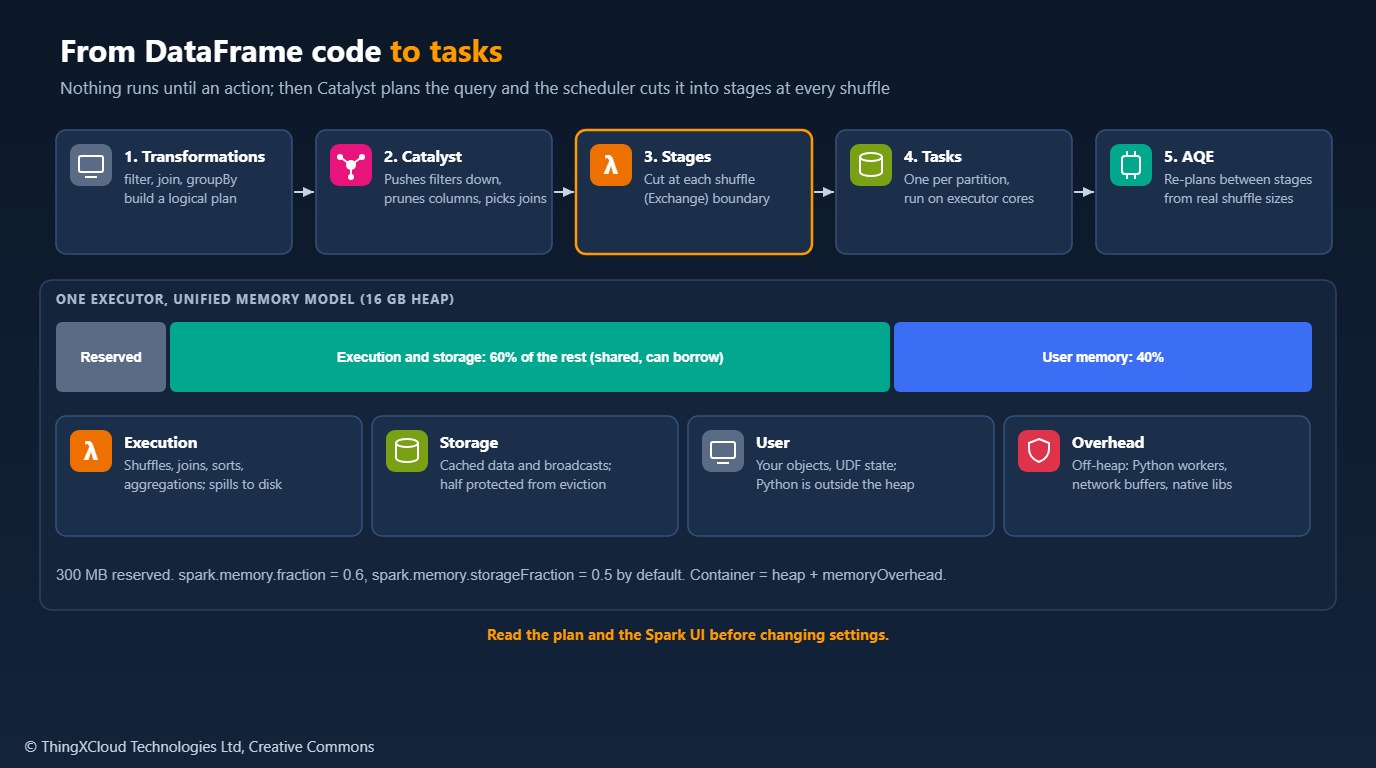
Transformations such as filter, select, join and groupBy only describe work. Nothing runs until an action such as count, collect or a write. At that point the Catalyst optimiser turns the logical plan into a physical plan: it pushes filters into the data source, reads only the columns needed and chooses join strategies. The scheduler then splits the physical plan into stages wherever rows must be redistributed by key, a shuffle, shown as an Exchange node in the plan. Within a stage, Spark runs one task per partition on the executors’ cores.
Narrow operations (filter, select, map) stay within a partition and cost little. Wide operations (groupBy, join, distinct, window functions, repartition) shuffle: every executor writes its rows to local disk, partitioned by key, and every task in the next stage fetches its share over the network. Shuffles dominate the cost of most slow jobs, so the first question for any job is how many shuffles it has and how much data each one moves.
Joins and Adaptive Query Execution
For joins Spark mainly chooses between a broadcast hash join, which copies the small side to every executor so the large side does not move, and a sort-merge join, which shuffles and sorts both sides by the key. Broadcasting is chosen when the small side is under spark.sql.autoBroadcastJoinThreshold (10 MB by default), estimated from statistics. Missing or stale statistics are the usual reason a large table is shuffled to join with a lookup table.
AQE, on by default since Spark 3.2, re-plans the query between stages using the real sizes of the shuffle output rather than estimates. It does three things: it coalesces many small shuffle partitions into fewer reasonable ones, it switches a sort-merge join to a broadcast join when one side turns out small, and it splits skewed partitions in joins so one hot key does not leave a single task running for an hour.
Read the plan instead of guessing
The sample’s helpers return the executed physical plan of a DataFrame after AQE has finalised it, count its shuffles, name the join strategy and measure partition skew for a key:
"""Small, testable helpers for looking inside Spark jobs (PySpark 4.0).

- `physical_plan`: the executed physical plan as text, after Adaptive Query
  Execution (AQE) has run, so you can see Exchanges (shuffles) and the join
  strategy Spark actually chose.
- `count_exchanges`, `join_strategy`: read those facts from the plan.
- `partition_skew`: rows per partition and the max/median ratio, to spot
  skew before it becomes one straggling task.
- `executor_memory`: the unified memory model arithmetic for an executor.

Uses the classic (non-Connect) PySpark API, which exposes the JVM query
execution; Spark Connect clients would read the same plan from the UI or
`df.explain(mode="formatted")`.
"""
from __future__ import annotations

import re
import statistics
from dataclasses import dataclass

from pyspark.sql import DataFrame, functions as F

RESERVED_MB = 300            # fixed by Spark for internal objects


def physical_plan(df: DataFrame) -> str:
    """Executed plan after an action, including AQE's final decisions."""
    qe = df._jdf.queryExecution()
    qe.toRdd().count()                                  # run this exact plan so AQE finalises it
    return qe.executedPlan().toString()


def count_exchanges(plan: str) -> int:
    """Shuffle exchanges in a plan (broadcast exchanges are not shuffles)."""
    return len(re.findall(r"(?<![A-Za-z])Exchange\b", plan))


def join_strategy(plan: str) -> str | None:
    for name in ("BroadcastHashJoin", "SortMergeJoin", "ShuffledHashJoin", "BroadcastNestedLoopJoin",
                 "CartesianProduct"):
        if name in plan:
            return name
    return None


@dataclass
class Skew:
    rows_per_partition: list[int]

    @property
    def ratio(self) -> float:
        nonzero = [r for r in self.rows_per_partition if r] or [0]
        median = statistics.median(nonzero)
        return max(nonzero) / median if median else 0.0


def partition_skew(df: DataFrame, key: str, partitions: int) -> Skew:
    """Rows per partition if `df` were hash-partitioned on `key` into `partitions`."""
    counts = (df.repartition(partitions, key)
                .groupBy(F.spark_partition_id().alias("p")).count()
                .collect())
    by_p = {r["p"]: r["count"] for r in counts}
    return Skew([by_p.get(i, 0) for i in range(partitions)])


@dataclass(frozen=True)
class ExecutorMemory:
    heap_mb: int
    unified_mb: float        # execution + storage, shared
    storage_protected_mb: float
    user_mb: float


def executor_memory(heap_mb: int, memory_fraction: float = 0.6, storage_fraction: float = 0.5) -> ExecutorMemory:
    """Unified memory model: (heap - 300 MB) split between Spark's pool and user memory."""
    if heap_mb <= RESERVED_MB * 1.5:
        raise ValueError("executor heap must be at least 450 MB")
    usable = heap_mb - RESERVED_MB
    unified = usable * memory_fraction
    return ExecutorMemory(heap_mb, round(unified, 1), round(unified * storage_fraction, 1),
                          round(usable - unified, 1))
The tests make the behaviours above concrete on a local session: a filter adds no shuffle and a groupBy adds one; a 1,000-row dimension is broadcast unless the threshold is disabled; AQE coalesces the default 200 shuffle partitions and without AQE all 200 remain; a key that holds 80 per cent of the rows gives a skew ratio far above an evenly spread key.
import pytest
from pyspark.sql import SparkSession, functions as F

import spark_lab as lab


@pytest.fixture(scope="module")
def spark():
    s = (SparkSession.builder.master("local[2]").appName("spark-internals-lab")
         .config("spark.ui.enabled", "false")
         .config("spark.sql.shuffle.partitions", "200")
         .getOrCreate())
    s.sparkContext.setLogLevel("ERROR")
    yield s
    s.stop()


@pytest.fixture(scope="module")
def frames(spark):
    orders = spark.range(0, 200_000).select(
        F.col("id").alias("order_id"),
        (F.col("id") % 1000).alias("customer_id"),
        (F.col("id") % 97).cast("double").alias("amount"))
    customers = spark.range(0, 1000).select(F.col("id").alias("customer_id"),
                                             (F.col("id") % 5).alias("segment"))
    return orders, customers


def test_transformations_are_lazy_until_an_action(spark, frames):
    orders, _ = frames
    tracker = spark.sparkContext.statusTracker()
    before = set(tracker.getJobIdsForGroup())
    plan = orders.filter(F.col("amount") > 50).groupBy("customer_id").agg(F.sum("amount"))
    assert set(tracker.getJobIdsForGroup()) == before          # nothing ran yet
    plan.count()
    assert set(tracker.getJobIdsForGroup()) - before            # the action ran jobs


def test_groupby_introduces_a_shuffle(frames):
    orders, _ = frames
    narrow = orders.filter(F.col("amount") > 50).select("order_id")
    wide = orders.groupBy("customer_id").agg(F.sum("amount").alias("total"))
    assert lab.count_exchanges(lab.physical_plan(narrow)) == 0
    assert lab.count_exchanges(lab.physical_plan(wide)) >= 1


def test_small_dimension_is_broadcast_unless_disabled(spark, frames):
    orders, customers = frames
    joined = orders.join(customers, "customer_id")
    assert lab.join_strategy(lab.physical_plan(joined)) == "BroadcastHashJoin"
    spark.conf.set("spark.sql.autoBroadcastJoinThreshold", "-1")
    spark.conf.set("spark.sql.adaptive.enabled", "false")
    try:
        assert lab.join_strategy(lab.physical_plan(orders.join(customers, "customer_id"))) == "SortMergeJoin"
    finally:
        spark.conf.unset("spark.sql.autoBroadcastJoinThreshold")
        spark.conf.unset("spark.sql.adaptive.enabled")


def test_aqe_coalesces_small_shuffle_partitions(spark, frames):
    orders, _ = frames
    agg = orders.groupBy("customer_id").agg(F.sum("amount"))
    spark.conf.set("spark.sql.adaptive.enabled", "true")
    plan_on = lab.physical_plan(agg)
    assert "AQEShuffleRead" in plan_on and "coalesced" in plan_on
    spark.conf.set("spark.sql.adaptive.enabled", "false")
    try:
        plan_off = lab.physical_plan(orders.groupBy("customer_id").agg(F.sum("amount")))
        assert "AQEShuffleRead" not in plan_off and ", 200)" in plan_off   # all 200 partitions kept
    finally:
        spark.conf.unset("spark.sql.adaptive.enabled")


def test_partition_skew_detects_a_hot_key(spark):
    even = spark.range(0, 100_000).select((F.col("id") % 100).alias("k"))
    hot = spark.range(0, 100_000).select(F.when(F.col("id") % 10 < 8, F.lit(0))
                                         .otherwise(F.col("id") % 100).alias("k"))
    assert lab.partition_skew(even, "k", 8).ratio < 1.5
    assert lab.partition_skew(hot, "k", 8).ratio > 4


def test_executor_memory_model():
    m = lab.executor_memory(16 * 1024)                 # 16 GiB heap
    assert m.unified_mb == pytest.approx((16384 - 300) * 0.6, abs=0.1)
    assert m.storage_protected_mb == pytest.approx(m.unified_mb / 2, abs=0.1)
    assert m.user_mb == pytest.approx((16384 - 300) * 0.4, abs=0.1)
    with pytest.raises(ValueError):
        lab.executor_memory(400)
%%{init: {'theme': 'base', 'themeVariables': {'primaryColor': '#FFF3E0', 'primaryTextColor': '#232F3E', 'primaryBorderColor': '#FF9900', 'lineColor': '#232F3E', 'clusterBkg': '#F8FAFC', 'clusterBorder': '#CBD5E1', 'edgeLabelBackground': '#FFFFFF', 'nodeTextColor': '#232F3E'}}}%%
flowchart TD
A["Slow stage in the Spark UI"] --> B{"One task much<br/>longer than the median?"}
B -- "Yes" --> C["Skew: check the key,<br/>AQE skew join, salt it"]
B -- "No" --> D{"Spill bytes above zero?"}
D -- "Yes" --> E["Partitions too large:<br/>more partitions or memory"]
D -- "No" --> F{"Large shuffle for<br/>a small table?"}
F -- "Yes" --> G["Broadcast the small side,<br/>refresh statistics"]
F -- "No" --> H{"Thousands of tiny tasks?"}
H -- "Yes" --> I["Compact input files,<br/>check coalescing"]
H -- "No" --> J["Profile the code:<br/>Python UDFs, I/O, GC"]
classDef aws fill:#FFF3E0,stroke:#FF9900,stroke-width:2px,color:#232F3E
classDef ok fill:#F0FFF4,stroke:#1D8102,stroke-width:2px,color:#145202
class A,B,D,F,H aws
class C,E,G,I,J okPartitions, skew and memory
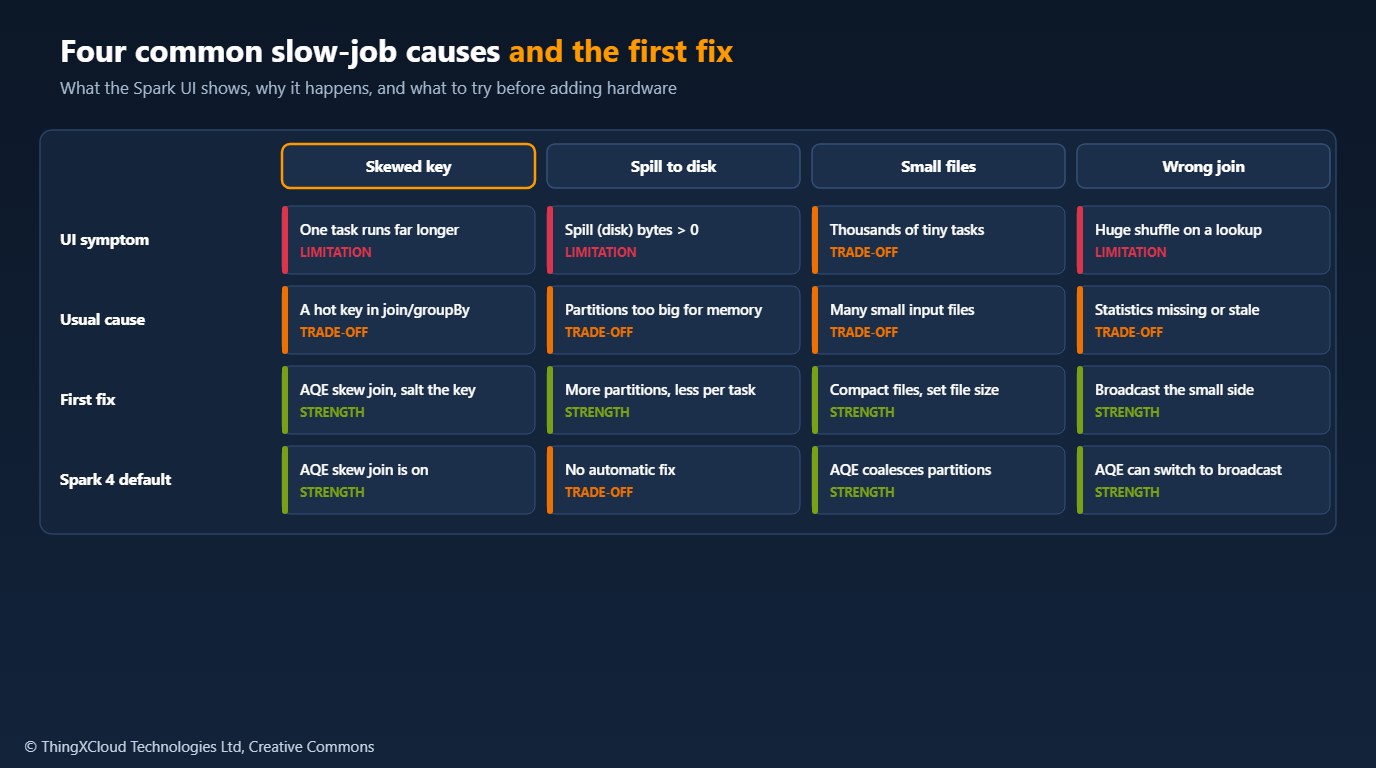
A task processes one partition, so partition size decides both parallelism and memory pressure. Aim for shuffle partitions of roughly 100 to 200 MB; far smaller and scheduling overhead dominates, far larger and tasks spill. spark.sql.shuffle.partitions defaults to 200, which AQE adjusts downwards but not upwards, so very large shuffles may need it raised. Skew is the exception partitions cannot fix: when one key holds a large share of the rows, its partition is large whatever the count. AQE splits skewed join partitions; for aggregations, adding a random salt to the key and aggregating twice spreads the work.
Executor memory follows the unified model. Spark reserves 300 MB, then gives spark.memory.fraction (0.6) of the rest to a shared pool for execution (shuffles, joins, sorts, aggregations) and storage (cached data, broadcasts), with half of it protected for storage by spark.memory.storageFraction. The remaining 40 per cent is user memory for your own objects. Python workers, network buffers and native libraries live outside the heap in spark.executor.memoryOverhead, which is why PySpark jobs killed by the container manager usually need more overhead, not more heap.
Caching helps only when the same DataFrame is used by several actions and recomputing it is expensive. Cache, use, then unpersist; caching everything fills storage memory, evicts data that mattered and pushes execution into spills.
Shuffle files on executor disks and rows printed to driver logs contain the data being processed. Encrypt local disks and shuffle traffic where the data is sensitive (Spark supports I/O encryption), keep row-level data out of logs, and make sure clean-up of shuffle files and event logs follows your retention rules.
The sample was tested with Python 3.12, pyspark==4.0.1 (September 2025), OpenJDK 21 and pytest==8.4.2 in local[2] mode: six tests cover lazy evaluation, shuffle counts, broadcast versus sort-merge joins, AQE coalescing, skew measurement and the memory arithmetic. Spark 4.0 changes are from the Spark 4.0.0 release notes. The partition size range is a common starting point, not a Spark default.
Key takeaways
- Spark 4.0 requires JDK 17, turns ANSI mode on and removes Mesos; test existing jobs before upgrading.
- Transformations are lazy; an action triggers planning, and every shuffle (Exchange) starts a new stage.
- Broadcast small tables, keep statistics fresh, and let AQE coalesce partitions, switch joins and split skew.
- Size partitions for memory, treat a single long task as skew, and salt hot keys AQE cannot handle.
- Know the memory model: 300 MB reserved, 60 per cent shared for execution and storage, overhead outside the heap.
What was the hardest Spark performance problem you traced, and what did the plan or the UI show? Share it in the comments.
The complete sample for this article is on GitHub: nithinmohantk/blog-samples-working-repo/spark-internals-lab. Clone it with git clone https://github.com/nithinmohantk/blog-samples-working-repo.git and open the spark-internals-lab folder. Its README says how to run it and what has been verified.
Glossary
- Stage
- A set of tasks that run without moving data between executors; stages are separated by shuffles.
- Shuffle
- Redistributing rows across executors by key, written to disk and fetched over the network.
- Exchange
- The physical plan node that represents a shuffle.
- Broadcast join
- A join that copies the small side to every executor so the large side does not shuffle.
- AQE
- Adaptive Query Execution: re-planning between stages using real data sizes.
- Skew
- Uneven distribution of rows across partitions, usually caused by hot keys.
- Spill
- Writing intermediate data to disk when execution memory runs out.
- ANSI mode
- Spark SQL behaviour that follows the SQL standard, raising errors on invalid operations.
References & Further Reading
- → Spark Release 4.0.0— Release notes: JDK 17, Scala 2.13, Spark Connect, ANSI mode
- → Building the Modern Data Stack (this blog)— Where Spark fits alongside Kafka and dbt
- → Sample code for this article— Plan, join, AQE, skew and memory helpers with tests
Discover more from C4: Container, Code, Cloud & Context
Subscribe to get the latest posts sent to your email.
