
On this page
Azure OpenAI Service offers OpenAI’s models inside an Azure subscription, with Azure identity, networking, quotas and regional deployment options. From Python it is reached through the same openai package used for OpenAI’s own API, with an AzureOpenAI client. The differences are small in code and large in operation: models are called through named deployments, every request carries an API version, authentication can and should use Microsoft Entra ID instead of keys, and the deployment type decides where prompts are processed.
This article sets out how to call Azure OpenAI from Python as of November 2024: client setup with keyless authentication, API versions, deployments and deployment types, structured outputs, and handling of throttling, content filtering, refusals and truncation. The sample code is a small, tested client module that does all of these.
Client, API version and authentication
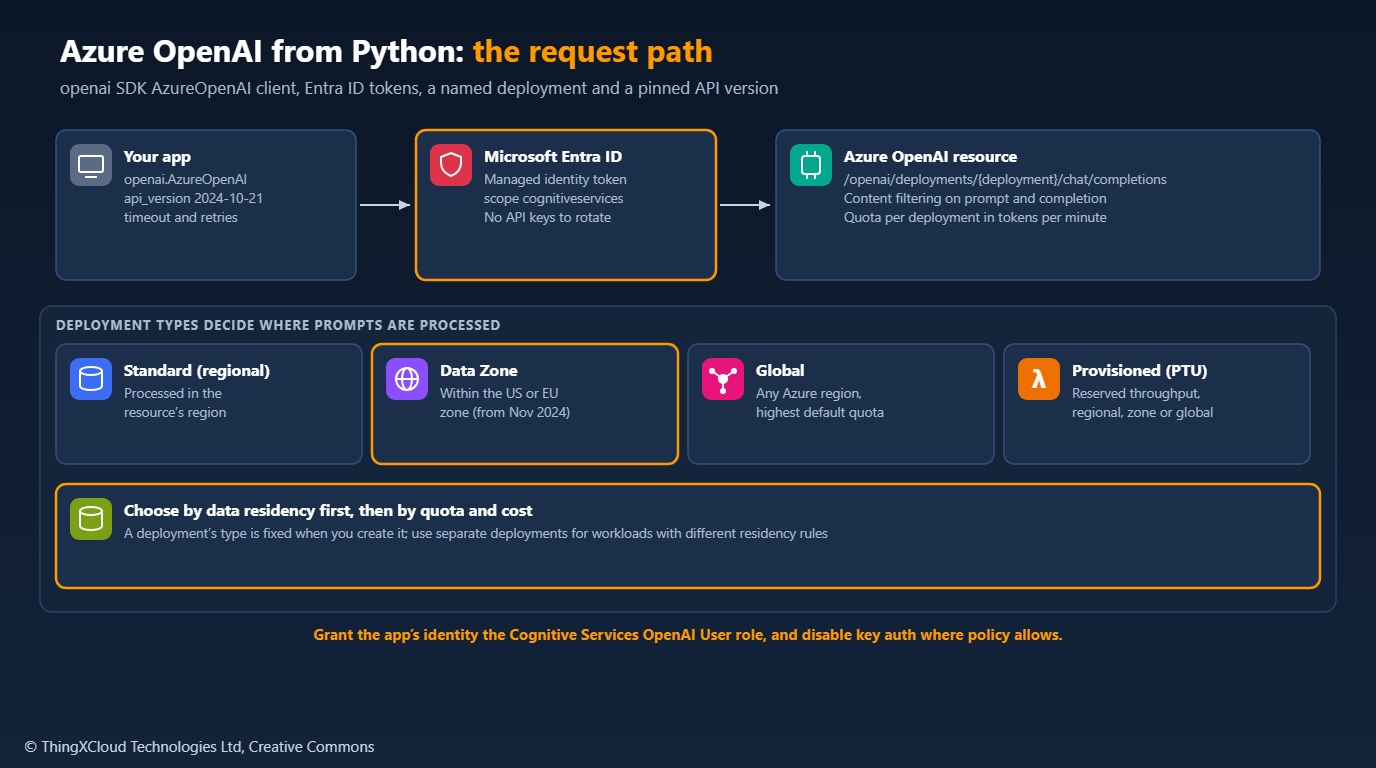
Every Azure OpenAI request names an API version. Microsoft’s documentation lists 2024-10-21 as the latest GA release, replacing the previous GA version 2024-06-01, with preview versions alongside it for newer features. Pin a GA version in configuration and move deliberately, because preview versions are retired on a schedule.
For authentication, use Entra ID rather than API keys. azure-identity‘s get_bearer_token_provider wraps a credential such as DefaultAzureCredential and returns a function the client calls for a fresh token, scoped to https://cognitiveservices.azure.com/.default. In Azure the credential resolves to the app’s managed identity; on a developer machine, to the developer’s login. Grant the identity the Cognitive Services OpenAI User role on the resource, and there is no secret to store, rotate or leak.
%%{init: {'theme': 'base', 'themeVariables': {'signalColor': '#0073BB', 'signalTextColor': '#0F172A', 'actorBkg': '#FFF3E0', 'actorBorder': '#FF9900', 'actorTextColor': '#232F3E', 'noteBkgColor': '#FFF8E7', 'noteBorderColor': '#FF9900', 'noteTextColor': '#232F3E', 'lineColor': '#232F3E'}}}%%
sequenceDiagram
    participant App as Python app
    participant Entra as Entra ID
    participant AOAI as Azure OpenAI
    App->>Entra: Token for cognitiveservices scope
    Entra-->>App: Bearer token, about one hour
    App->>AOAI: POST deployments/invoices-gpt4o/chat/completions
    Note over AOAI: Content filter on prompt,<br/>quota check per deployment
    AOAI-->>App: Completion, or 429 with retry-after
    Note over App: Token provider refreshes<br/>before expiry
Deployments and where data is processed
Code passes the deployment name where OpenAI’s API takes a model name. Each deployment fixes a model and version, a tokens-per-minute quota and a deployment type. The type decides where requests are processed: Standard deployments in the resource’s region; Global deployments in any Azure region, with the highest default quota; and since 1 November 2024, Data Zone deployments, which Microsoft made available for both Standard and Provisioned offerings and which keep processing within a Microsoft-defined zone such as the EU or the US. Provisioned deployments reserve throughput in provisioned throughput units for predictable latency.
Data stored at rest stays in the resource’s geography, but processing location follows the deployment type. If prompts may contain personal or regulated data that must stay in the EU, use Standard deployments in an EU region or Data Zone EU deployments, not Global, and record the choice in your data processing records. Use separate deployments for workloads with different rules.
Structured outputs
Asking a model for JSON and parsing whatever comes back fails in production. Structured outputs send a JSON schema with the request and constrain the model to it; with the openai SDK the schema can come from a Pydantic model, and client.beta.chat.completions.parse returns a validated object. The GA API version 2024-10-21 supports structured outputs on model versions that offer them, such as GPT-4o 2024-08-06.
The sample builds the client and extracts an invoice into a Pydantic model, returning a clear status for each way the call can go wrong:
"""Calling Azure OpenAI from Python with keyless auth and structured outputs.

- `make_client`: an `AzureOpenAI` client that authenticates with Microsoft
  Entra ID (managed identity in Azure, your developer login locally) through
  `azure-identity`, pins the GA API version, and sets timeouts and retries.
- `extract_invoice`: structured outputs. The response is validated against a
  Pydantic model; refusals, content-filter blocks and truncated answers are
  reported as distinct outcomes instead of exceptions deep in parsing.

Environment:
    AZURE_OPENAI_ENDPOINT    https://<resource>.openai.azure.com
    AZURE_OPENAI_DEPLOYMENT  the deployment name (not the model name)
    AZURE_OPENAI_API_VERSION optional, defaults to the GA version 2024-10-21
"""
from __future__ import annotations

import os
from dataclasses import dataclass
from typing import Callable

from openai import AzureOpenAI, BadRequestError, ContentFilterFinishReasonError, LengthFinishReasonError
from pydantic import BaseModel, Field

GA_API_VERSION = "2024-10-21"
SCOPE = "https://cognitiveservices.azure.com/.default"


def make_client(endpoint: str | None = None, api_version: str | None = None,
                token_provider: Callable[[], str] | None = None, **kwargs) -> AzureOpenAI:
    """Build a client that uses Entra ID tokens; no API key is read or stored."""
    endpoint = endpoint or os.environ["AZURE_OPENAI_ENDPOINT"]
    if token_provider is None:
        from azure.identity import DefaultAzureCredential, get_bearer_token_provider
        token_provider = get_bearer_token_provider(DefaultAzureCredential(), SCOPE)
    return AzureOpenAI(
        azure_endpoint=endpoint,
        api_version=api_version or os.environ.get("AZURE_OPENAI_API_VERSION", GA_API_VERSION),
        azure_ad_token_provider=token_provider,
        timeout=kwargs.pop("timeout", 60.0),
        max_retries=kwargs.pop("max_retries", 3),      # 429 and 5xx, honouring retry-after
        **kwargs,
    )


class LineItem(BaseModel):
    description: str
    quantity: float
    unit_price: float


class Invoice(BaseModel):
    supplier: str
    invoice_number: str
    currency: str = Field(description="ISO 4217 code, for example EUR")
    total: float
    lines: list[LineItem]


@dataclass
class Outcome:
    status: str                    # "ok", "refused", "filtered", "truncated"
    invoice: Invoice | None = None
    detail: str = ""
    prompt_tokens: int = 0
    completion_tokens: int = 0


SYSTEM = ("Extract the invoice fields from the user's text. Use only values present in the text. "
          "If a value is missing, use an empty string or 0.")


def extract_invoice(client: AzureOpenAI, deployment: str, text: str) -> Outcome:
    try:
        resp = client.beta.chat.completions.parse(
            model=deployment,                          # Azure: the deployment name
            messages=[{"role": "system", "content": SYSTEM}, {"role": "user", "content": text}],
            response_format=Invoice,
            temperature=0,
            max_tokens=800,
        )
    except LengthFinishReasonError:
        # The SDK will not parse a cut-off JSON answer
        return Outcome("truncated", detail="raise max_tokens or shorten the input")
    except ContentFilterFinishReasonError:
        return Outcome("filtered", detail="completion blocked by content filtering")
    except BadRequestError as exc:
        body = exc.body if isinstance(exc.body, dict) else {}
        if body.get("code") == "content_filter":
            return Outcome("filtered", detail="prompt blocked by content filtering")
        raise
    choice = resp.choices[0]
    usage = (resp.usage.prompt_tokens, resp.usage.completion_tokens) if resp.usage else (0, 0)
    if choice.message.refusal:
        return Outcome("refused", detail=choice.message.refusal, prompt_tokens=usage[0], completion_tokens=usage[1])
    return Outcome("ok", invoice=choice.message.parsed, prompt_tokens=usage[0], completion_tokens=usage[1])
Failure handling
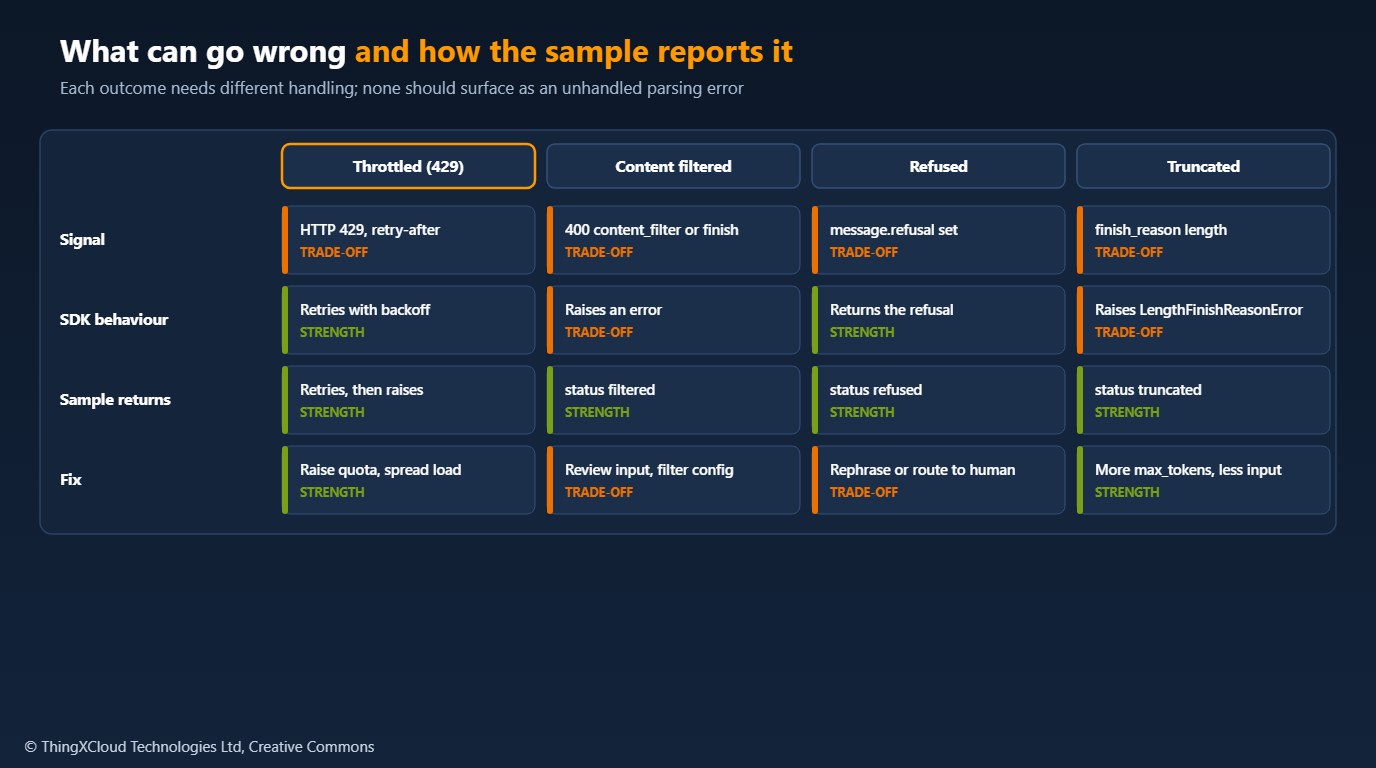
- Throttling. When a deployment exceeds its quota, Azure OpenAI returns HTTP 429 with a retry-after header. The SDK retries with backoff (
max_retries, default 2; the sample uses 3). Persistent 429s mean the deployment needs more quota, or load should be spread across deployments or regions. - Content filtering. Azure applies content filters to prompts and completions. A blocked prompt returns HTTP 400 with the code
content_filter; a blocked completion ends with that finish reason. Log these separately from errors, because the fix is a review of the input or the filter configuration, not a retry. - Refusals. With structured outputs, a model that declines returns a
refusalmessage instead of the schema. Route these to a person or a fallback. - Truncation. If the answer hits
max_tokens, the JSON is incomplete and the SDK refuses to parse it. Raise the limit or send less input.
The tests run the client against a mocked endpoint and check the request itself: the deployment path, the API version, a bearer token and no API key, and a strict schema in response_format.
import json

import httpx
import pytest
from openai import BadRequestError

import aoai

INVOICE = {"supplier": "Contoso Ltd", "invoice_number": "INV-1042", "currency": "EUR", "total": 240.0,
           "lines": [{"description": "Licences", "quantity": 4, "unit_price": 60.0}]}


def client_with(handler, seen):
    def wrapped(request: httpx.Request) -> httpx.Response:
        seen.append(request)
        return handler(request)
    return aoai.make_client(endpoint="https://contoso.openai.azure.com", token_provider=lambda: "entra-token",
                            max_retries=0, http_client=httpx.Client(transport=httpx.MockTransport(wrapped)))


def completion(content=None, finish="stop", refusal=None):
    return httpx.Response(200, json={
        "id": "c1", "object": "chat.completion", "created": 1731800000, "model": "gpt-4o-2024-08-06",
        "choices": [{"index": 0, "finish_reason": finish,
                     "message": {"role": "assistant", "content": content, "refusal": refusal}}],
        "usage": {"prompt_tokens": 210, "completion_tokens": 64, "total_tokens": 274}})


def test_request_uses_deployment_path_ga_version_bearer_token_and_schema():
    seen = []
    c = client_with(lambda r: completion(json.dumps(INVOICE)), seen)
    out = aoai.extract_invoice(c, "invoices-gpt4o", "Invoice INV-1042 from Contoso Ltd ...")
    req = seen[0]
    assert req.url.path == "/openai/deployments/invoices-gpt4o/chat/completions"
    assert req.url.params["api-version"] == "2024-10-21"
    assert req.headers["authorization"] == "Bearer entra-token"
    assert "api-key" not in req.headers
    body = json.loads(req.content)
    assert body["response_format"]["type"] == "json_schema"
    assert body["response_format"]["json_schema"]["strict"] is True
    assert out.status == "ok" and out.invoice.total == 240.0 and out.invoice.lines[0].quantity == 4
    assert (out.prompt_tokens, out.completion_tokens) == (210, 64)


def test_refusal_is_reported():
    out = aoai.extract_invoice(client_with(lambda r: completion(None, refusal="I can't help with that."), []),
                               "d", "text")
    assert out.status == "refused" and "can't" in out.detail


def test_completion_content_filter_is_reported():
    out = aoai.extract_invoice(client_with(lambda r: completion(None, finish="content_filter"), []), "d", "text")
    assert out.status == "filtered"


def test_prompt_content_filter_400_is_reported():
    err = {"error": {"message": "The response was filtered", "type": None, "param": "prompt",
                     "code": "content_filter", "status": 400}}
    out = aoai.extract_invoice(client_with(lambda r: httpx.Response(400, json=err), []), "d", "text")
    assert out.status == "filtered"


def test_other_400_errors_are_raised():
    err = {"error": {"message": "bad", "type": "invalid_request_error", "code": "invalid_value"}}
    with pytest.raises(BadRequestError):
        aoai.extract_invoice(client_with(lambda r: httpx.Response(400, json=err), []), "d", "text")


def test_truncated_answer_is_reported_without_parsing():
    seen = []
    def handler(r):
        return completion('{"supplier": "Cont', finish="length")
    out = aoai.extract_invoice(client_with(handler, seen), "d", "text")
assert out.status == "truncated"After every caller uses Entra ID, turn off key-based authentication on the resource (the disableLocalAuth property) where your policy allows. It removes the risk of a leaked key and makes the Azure activity and sign-in logs the single record of who called the service.
A deployment can follow a model’s default version and be upgraded automatically. For workloads validated against a specific behaviour, pin the model version on the deployment and plan upgrades before the version’s retirement date, re-running your evaluation first.
aoai.py was tested with Python 3.12, openai==1.54.4, azure-identity==1.19.0, pydantic==2.9.2, httpx==0.27.2 and pytest==8.3.3: six tests against a mocked endpoint cover the request path, API version, bearer token, strict schema, parsing, refusals, content filtering on prompt and completion, other errors and truncation. No Azure resource was called. API versions and Data Zone availability are from Microsoft’s documentation and announcement.
Key takeaways
- Use the openai package’s AzureOpenAI client, pin the GA API version (2024-10-21 as of November 2024) and set timeouts and retries.
- Authenticate with Entra ID through a token provider and managed identity; then disable key authentication.
- Call deployments, not models; the deployment type (Standard, Data Zone, Global, Provisioned) decides where prompts are processed.
- Use structured outputs with a Pydantic model instead of parsing free-form JSON.
- Handle throttling, content filtering, refusals and truncation as distinct outcomes.
How are you choosing between Standard, Data Zone and Global deployments for your workloads? Share your reasoning in the comments.
The complete sample for this article is on GitHub: nithinmohantk/blog-samples-working-repo/azure-openai-client. Clone it with git clone https://github.com/nithinmohantk/blog-samples-working-repo.git and open the azure-openai-client folder. Its README says how to run it and what has been verified.
Glossary
- Deployment
- A named instance of a model version in an Azure OpenAI resource, with its own quota and type.
- API version
- The dated version of the Azure OpenAI REST API sent with every request.
- Entra ID
- Microsoft’s identity service, formerly Azure Active Directory.
- Managed identity
- An Azure-managed identity for a workload, used to get tokens without secrets.
- Data Zone deployment
- A deployment type that processes requests within a Microsoft-defined zone such as the EU.
- Structured outputs
- Constraining a model’s response to a supplied JSON schema.
- PTU
- Provisioned throughput unit: reserved model processing capacity.
References & Further Reading
- → Azure OpenAI API version lifecycle— 2024-10-21 as the latest GA release
- → Keyless authentication methods— get_bearer_token_provider with the cognitiveservices scope
- → Accelerate scale with Azure OpenAI Service Provisioned offering— Data Zones for Standard and Provisioned from 1 November 2024
- → Sample code for this article— Keyless client, structured outputs and failure handling
Discover more from C4: Container, Code, Cloud & Context
Subscribe to get the latest posts sent to your email.
